Learning to Stop Writing Code

...and why you won't miss it

Daisy Hollman

Berkeley AI Hackathon 2025
daisyh.dev/talks/berkeley-2025
This presentation is optimized for a 16:10 aspect ratio. Please resize your browser window or rotate your device for the best viewing experience.

Who am I?

  • I work on AI at Anthropic
  • Before that: Google, Sandia National Labs
  • Background in C++, quantum chemistry
  • Interested in how AI changes the way we write code

Overview

  • How do LLMs work?
    • Architecture & Inference
    • Training
    • Agents
  • Coding with LLMs
    • What they're good at
    • What they're bad at (so far)
  • Claude Code Best Practices
    • Customize your setup
    • Give Claude more tools
    • Common workflows
    • Optimize your workflow

How do LLMs work?


A conceptual overview of LLMs that's good enough for the purposes of this talk (but also definitely wrong in very very many ways)

Disclaimer: I'm not an expert on LLM training, or inference, or AI, or machine learning, but this picture of the world has been helpful for me as a software engineer who needs to use LLMs.

LLM Architecture

Overview of a typical modern LLM architecture

LLM Architecture

  • This layer turns tokens into vectors
  • But there is a limit to the number of input tokens that the model has been trained on
    • This is called the "context window" or "context length"
    • Basically everything built on top of LLMs is about engineering ways to efficiently use this context window

Spoiler: Almost all of the best practices for coding with LLMs that I'm going to talk about revolve around this.

Overview of a typical modern LLM architecture

LLM Architecture: Transformers

  • _____ Is All You Need
    • Attention!
      Overview of a typical modern LLM architecture
  • Transformers build connections between related tokens that may be far from each other in the input.
Overview of a typical modern LLM architecture

LLM Architecture: Attention

Attention sentence diagram
Attention matrix diagram

LLM Architecture: Outputs

  • The output of the model is a probability distribution of possible next tokens
  • The model "chooses" the next token based on this distribution (This is called "sampling")
    • The "temperature" parameter controls how random the sampling is
    • Low temperature (close to 0) makes the model more deterministic
    • High temperature (around 1.0 or higher) makes the model more creative and random
  • The output is then added to the context window and the process repeats
Overview of a typical modern LLM architecture

LLM Architecture: Context Window

  • How do we get the model to "remember" previous prompts and responses over the course of a conversation?
  • It's shockingly primitive: just add special tokens (Human: and Assistant:) to separate prompt from response, and throw it all into the context window. Literally:
  • This means that long conversations can use a lot of tokens very quickly!

Training LLMs

LLM

Training LLMs

  • "Go read the whole internet"
    • Generally, the largest source of input data comes from scraping the internet
    • Books, academic papers, images, etc., are other sources
    • Frontier models started "running out of data" a long time ago, and we've been getting creative about ways to get more data for this step.
LLM

Training LLMs: Pre-training

  • Starts with random values for all of the weights (variables) in the model
  • (Very, very, very oversimplified) "Perturb the weights," and "see what happens"
    • If the model predicts the next token more accurately (i.e., matches the training data) with the new weights, keep them
    • (What actually happens is that we find a gradient and take a step in that direction, but this is also partially a lie)
  • Repeat until the model's weights stop changing (within some tolerance)
LLM

Training LLMs: Reinforcement Learning

  • Give the model a task with a reward signal
    • e.g., "make the tests in this code base pass"
  • Perturb the weights, and "see what happens"
    • If the model does better, keep the new weights
    • Again, updates are actually roughly based on gradient descent, but that's very old and oversimplified
  • Repeat for many different versions of "task" and "reward"
LLM

Agents

  • "Simple" LLM assistants operate on a prompt-response loop
  • Agents generally execute multi-step tasks with much more autonomy.
  • Other key characteristics of agents include:
    • Tool use
    • Planning and reasoning
    • Decision-making
    • Feedback-driven self-improvement
    • Goal-directed behavior
  • Importantly, though: agents are still limited by their context window!

Agents: Tool Use

  • At some point we realized that JSON is "just" text
  • So we started giving the LLMs a description of the JSON format for a tool and telling then what it does.
  • We can put anything we want on the other side of that tool
    • Most basically, "run this command in the terminal"
    • But we can also give it access to code repositories, databases, etc.
    • Importantly, it can make sure that its code compiles and passes tests
    • This is a critical piece of feedback for self-improvement!

Agents: Code Search Tool

  • How do agents understand a 1M+ line codebase with only a few hundred thousand tokens of context?
  • Maybe a better question: how do humans do this?
    • We search through the code for key entry points (e.g., main()),
    • …then we read code called by those entry points...
    • …and types and key data structures.
    • When we want to understand a specific piece of functionality, we search for key strings or patterns related to that functionality
    • In other words, we only "load" part of the code into our "context window"
    • And maybe we "load" as summary of the rest of the code (and how it works) into our "context window" if we've been working on the project for a while
  • Agents can do this too!

Coding with LLMs


AI is really good at helping you understand code

My "red pill" moment

  • Anthropic monorepo: ~500k lines of code
    • Mostly in languages I haven't used professionally in the past decade (Python, Rust, and TypeScript)
  • My third day at Anthropic:
    • "Make <feature I've never heard of> faster using <tool I've never heard of>, or maybe <other tool I've never heard of>"
    • …oh, and this change will impact every production image build we do.
    • Colleague: "I'll give you a tour of the codebase tomorrow"
    • Me: "I wonder if Claude knows how to do this"
    • …three hours later: pull request is ready.
    • Colleague, next morning: "So I see you sent me a pull request before I even gave you a tour of the codebase..."

AI is really good at helping you understand code


LLMs Understand Build Systems and Repository Management

My code isn't linking, and I think it's because there's something wrong with the build system. Please fix this for me.

Please cherry-pick the changes related to the Foo feature and apply them to the bar branch. Then ensure the tests are passing and create a pull request for that branch.

LLMs Are Really Good at Refactoring

I've made a change to run_baz(int). Take a look at this change using git diff and make the analogous change to the 57 other run_* functions in the same file.

Split up ExprConstant.cpp into smaller files. The smaller files should group together common functionality and should generally not be more than about 500 lines. Make sure to update the build system, and use the git filter-repo command to make sure all of the new files retain the history from the larger file.

LLMs Are Surprisingly Good at Boilerplate Reduction

Look at foo.h and see if there are any ways you can think of to be more DRY.

The boilerplate in do_bar.rs (and in all of the analogous do_*.rs files) is distracting, brittle, and error prone. Please help me remove it by designing and implementing a proc macro that abstracts away this boilerplate.

The section that will likely be obsolete by the time this goes on YouTube...

What LLMs Are Bad At

What are LLMs bad at: anecdotal edition

Another slide that will probably be obsolete

  • Programs running the same source code in separate processes
    • One of the most common mistakes I've seen boils down to not understanding the separation of memory spaces
  • LLMs struggle to reason about tests or development environments with poor hermiticity
  • LLMs often "forget" to do things.
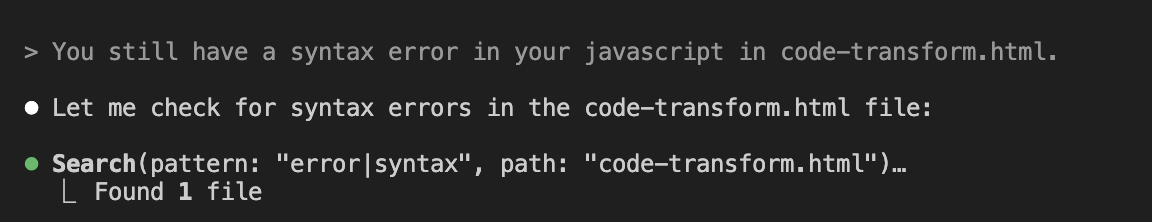
  • Like humans, LLMs sometimes get very confused or frustrated and do really dumb things:
    Oops

Reward Hacking

  • Basic idea: reward hacking is when a model learns to game the reward function in order to maximize its reward.
    • For instance, the model might replace a failing tests with ASSERT_TRUE(true);.
    • I actually caught it replacing the entire invocation of the test runner script with echo Success
  • This can happen in any context, but I've seen it happen most when I later realize that I was asking it to do something that isn't possible with the current setup.
  • It also means that, when acting autonomously, they often seem to right a lot of mocks, "fake" or "placeholder" implementations, and "sample" datastores into real code.
  • This feels like something that will be fixed in the next 3-6 months.

From the Anthropic engineering blog

Claude Code Best Practices

Create CLAUDE.md Files

Your AI assistant's documentation

  • Special file automatically pulled into context when starting a conversation
  • Can be placed at:
    • Root of repository
    • Parent/child directories (all loaded)
    • Home folder (~/.claude/CLAUDE.md)
  • Document:
    • Common bash commands and workflows
    • Code style guidelines
    • Testing instructions
    • Repository etiquette
    • Unexpected behaviors or warnings

Example CLAUDE.md

Real CLAUDE.md: Managing Long Projects

Real CLAUDE.md: Special Project Folders

Real CLAUDE.md: Development Logs

Real CLAUDE.md: Code Review Guidelines

Real CLAUDE.md: Git Workflow

Real CLAUDE.md: Pull Request Best Practices

Real CLAUDE.md: CI/CD Monitoring

Real CLAUDE.md: Language-Specific Tips

Tune Your CLAUDE.md Files

  • Refine them like frequently used prompts
  • Experiment to improve instruction following
  • Can add content:
    • Manually (edit the file)
    • Using the "#" key in Claude Code
  • Anthropic sometimes uses a "prompt improver" for internal projects

Curate Claude's Tool Permissions

Claude Code tool allowlist
  • Select "Always allow" during your session
  • Use /permissions command
  • Edit .claude/settings.json manually
  • Use --allowedTools CLI flag
  • Control which tools Claude can use in your environment

Give Claude More Tools

Extend capabilities beyond the defaults

  • Claude inherits your bash environment
  • Three ways to add tools:
    • Custom bash tools
    • Custom slash commands
    • MCP (Model Context Protocol)
  • For bash tools, provide instructions:
    • Tell Claude the tool name with examples
    • Use --help to show documentation
    • Document in CLAUDE.md

(I asked Claude to fill in this empty space with a meme and this is what it came up with)

Claude with default tools:

"I can read files 📄"

Claude with ALL the tools:

"I AM BECOME DEVELOPER,
DESTROYER OF BUGS 💪"

Custom Slash Commands

  • Store in .claude/commands folder
  • Can be project-specific or personal (~/.claude/commands)
  • Use $ARGUMENTS to pass parameters
  • Share across team via git

Common Workflows

Successful patterns for using Claude Code

  • Claude Code doesn't impose a specific workflow
  • Flexibility to use it how you want
  • Several proven patterns:
    • Explore, plan, code, commit
    • Visual iteration with screenshots
    • Safe YOLO mode
    • Git/GitHub integration

Explore, Plan, Code, Commit

  • Ask Claude to read relevant files without writing code
    • "Read the authentication module and understand how it works"
  • Have Claude make a plan using extended thinking
    • Use phrases like "think harder" or "think very hard" to activate extended thinking
  • Ask Claude to implement the solution
  • Ask Claude to commit and create a pull request

This workflow mirrors how human developers approach unfamiliar codebases

Visual Iteration Workflow

  • Screenshot → Claude implements → Screenshot → Iterate
  • Command-line screenshot tools Claude can use:
    • puppeteer - Node.js Chrome automation
    • playwright - Cross-browser (Chrome, Firefox, Safari)
    • chrome --headless --screenshot - Built-in
  • Perfect for UI/UX development and data visualization

Real Example: Making This Presentation Look Good

The actual prompt I used to improve these slides

Okay, now let's try something. You've researched a lot about how to do visual workflows. Think harder, then use one (probably puppeteer? but if that's not working try something else) to go through the slides and look for opportunities to improve the aesthetics. Optimize for both 16x9 (1080p or 4k; they should look roughly the same) and 16x10 (common aspect ratio for projectors). The slides are being hosted at localhost:8000, and you can pull up a particular fragment on a particular slide with, e.g., localhost:8000/#/5/0/3 for the 3rd fragment of the fifth slide. Keep the same style and themeing, but look for anything that looks awkward or uncomfortable in either of those aspect ratios. Start by writing yourself a script that can consistently capture screenshots (put it in your project scratch directory). Thanks for your help, and I'm looking forward to seeing your beautiful work!

Claude proceeded to write puppeteer scripts, capture screenshots, analyze layouts, and fix aesthetic issues across the entire presentation.

Safe YOLO Mode

When you trust Claude completely

Safe YOLO mode
  • Use claude --dangerously-skip-permissions
  • Bypasses all permission checks
  • Recommended only in isolated, offline containers
  • Great for rapid prototyping in safe environments

Git/GitHub Integration

  • Git operations:
    • Branches, commits, PRs
    • Cherry-pick changes
    • Analyze diffs
  • GitHub (gh CLI):
    • Manage issues
    • Submit PRs
    • Review comments
Fix GitHub issue #42 and create a PR with the solution
Address all comments in PR #123 and reply to each comment with links to the commits that fix them

Practical tips for effective AI collaboration

Optimize Your Workflow

Be Specific in Your Instructions

  • Clear, detailed instructions improve Claude's performance dramatically
  • Compare these two approaches:

❌ Poor

✅ Good

Give Claude Images

  • Three ways to provide visual context:
    • Paste screenshots directly
    • Drag and drop image files
    • Provide file paths to images
  • Particularly powerful for:
    • UI/UX development from design mocks
    • Debugging visual issues
    • Analyzing charts and graphs
Here's a screenshot of the UI bug. Can you help me fix the alignment issue in the navigation bar?

Use puppeteer to take screenshots of dashboard.html in various aspect ratios and make it more aesthetically pleasing

Mention Files You Want Claude to Look At

  • Use tab-completion to quickly reference files or folders
  • Be explicit about which files need attention
  • Examples:
    • "Update the tests in src/auth/login.test.ts"
    • "Refactor the utils/ directory to use TypeScript"
    • "Make sure changes are consistent with CONTRIBUTING.md"

Give Claude URLs

  • Paste specific URLs for Claude to fetch and read
  • Great for:
    • API documentation
    • Stack Overflow solutions
    • GitHub issues and PRs
    • Design specifications
  • Pro tip: Use /permissions to add domains to your allowlist
Implement the authentication flow described in https://docs.example.com/api/auth

Course Correct Early and Often

  • Four powerful tools for course correction:
    • Ask Claude to make a plan before coding
    • Press Escape to interrupt Claude
    • Double-tap Escape to jump back in history
    • Ask Claude to undo changes
Actually, let's take a different approach. Can you undo those changes and instead implement it using the strategy pattern?

Pass Data Into Claude

  • Multiple methods to provide data:
    • Copy and paste directly
    • Pipe data into Claude Code: npm test | claude
    • Ask Claude to pull data: "Run curl to get the API response"
    • Have Claude read files or fetch URLs
  • Choose the method that fits your workflow
Run `docker logs myapp` and analyze any errors in the output

Questions?